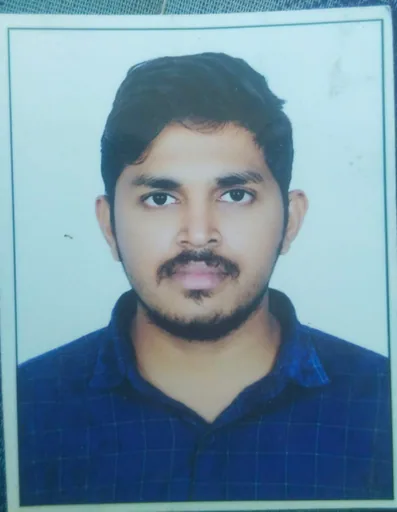
SANAPALA N.
Mid-Level Data Engineer
Open to offersNew to PlatformAbout
Teja S. is a Data Engineer with over three years of specialized experience in building and maintaining Azure Databricks-based data pipelines for the car leasing industry. Primarily focusing on near real-time reporting, he led BNP Paribas in adopting medallion architecture and implementing SCD Type 1, which resulted in a 30% reduction in data errors and quicker report refresh cycles. His proficiency extends to cleansing, enriching, and standardizing data in the Databricks silver layer to ensure analytics-ready datasets. Since May 2022, Teja has been instrumental in managing scalable ETL pipelines using Azure Data Factory and Databricks for business intelligence purposes. He has designed materialized views to augment report performance for Power BI users and introduced Spark solutions to minimize bad data incidents by 30%. Known for his leadership in CI/CD initiatives, he ensures reliable pipeline updates and governance, all while mentoring junior engineers in data modeling and Spark optimization techniques. Teja holds certifications in Azure Data Fundamentals and Azure Data Engineer Associate.
Experience
Data Engineer
null · 2022 — PresentManaged ETL pipelines using Azure Data Factory and Databricks for ingesting, cleansing, and transforming leasing and fleet data to support business intelligence. Designed and sustained medallion architecture bronze and silver layers with SCD Type 1 for historical data tracking. Created materialized views in Azure Databricks to provide efficiently aggregated datasets for the Power BI team. Developed Spark solutions and established automated validation checks to monitor data quality, resulting in a reduction of bad data incidents. Spearheaded CI/CD initiatives, integrating automated testing and deployment pipelines to ensure dependable production pipeline updates. Worked closely with analytics and business teams to define key performance indicators (KPIs) such as fleet utilization rate and lease revenue, facilitating actionable insights for strategic decisions. Guided junior data engineers in best practices regarding data modeling, ETL design patterns, and optimization techniques related to Spark.
Skills & Expertise
Education
- Manufacturing engineeringUniversity Of Hyderabad · 2020 — 2022
Interested in this professional?
Sign in as an employer to save this profile or invite SANAPALA N. to a job.
Sign in as an employer